
Web Scraping APIs: Proxy, Rendering and Parsing Explained
Understand the separate responsibilities behind a web-data request and define the output contract before choosing a managed API or your own worker.
KAIROXO
A web scraping API wraps part of the journey from a URL to useful data. Understanding that journey helps a team ask better integration questions: who owns network access, who executes JavaScript, who extracts fields and who decides whether the result satisfies the business requirement?
Those responsibilities can be combined in a managed service or split across an application. The right boundary depends on the task and the actual contract, rather than the word API alone. Start by defining the expected result for a small set of authorized public pages, then work backward to the capabilities needed.
Describe the output before selecting the tool
Write down required fields, source identity, collection time, acceptable freshness and what an empty result means. A monitoring job may only need a page title and status, while a catalog job may require product identity, currency and availability. These are different acceptance criteria even when they start from the same URL.
Choose a representative sample with a normal page, missing content, an inaccessible page and a layout variation. Define whether failures appear as HTTP errors, structured outcome records or asynchronous job states according to the service. Keep that mapping explicit so downstream code does not interpret every nonempty response as success.
Separate the layers behind one request
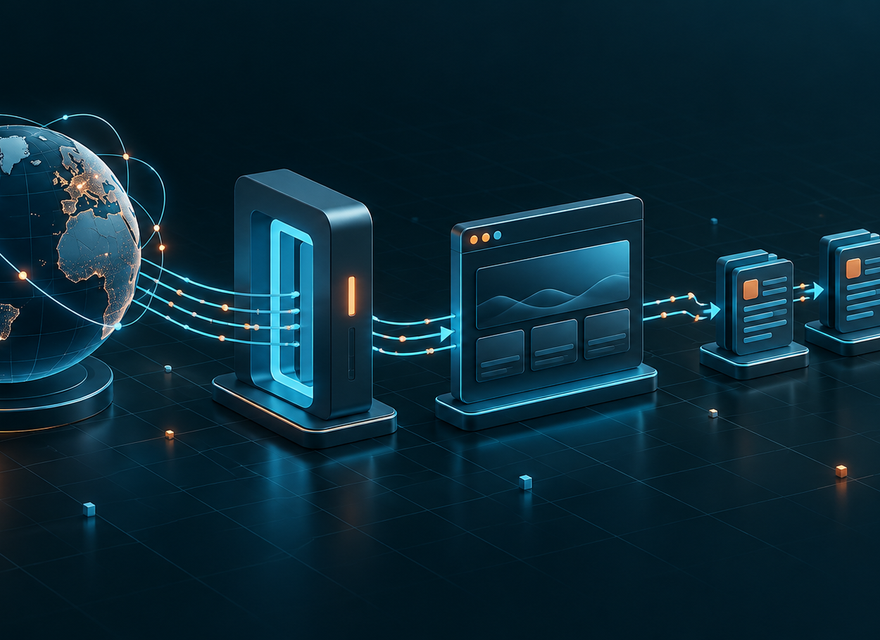
The network layer connects the worker to the destination, possibly through an explicitly selected proxy profile. Rendering executes a page when the required content depends on browser behavior. Parsing interprets the retrieved HTML, rendered document or structured response. Validation decides whether the extracted values are complete and plausible for the task.
Each stage can fail independently. A valid proxy connection can retrieve an unexpected page; successful rendering can still produce no required fields; a parser can return syntactically valid JSON with the wrong meaning. Keep stage-level outcomes or equivalent diagnostic evidence so the application can identify where useful data was lost.
Understand what a proxy contributes
A proxy supplies a network route and may expose supported region or session settings. It does not automatically execute a site's JavaScript, select the right product variant or normalize a price. Those tasks belong to other parts of the pipeline unless a managed service explicitly includes them.
For a team with an existing HTTP client or browser worker, direct proxy integration can preserve control over the rest of the stack. That control also means owning scheduling, deadlines, retries, parsing and quality checks. Evaluate the full workload, including maintenance, when deciding where the managed-service boundary belongs.
Decide when rendering is necessary
Inspect whether required data is available in the response you are allowed to retrieve. Some pages provide enough information without a browser, while others populate important content after script execution. Rendering every page can add avoidable compute and latency; omitting it when required produces empty or incomplete records.
Verify rendering support and controls against the chosen endpoint. Do not assume that a service advertised as a crawler includes arbitrary browser interactions, persistent login, a particular wait condition or every output format. Document the exact supported behavior for the target and keep a small test that demonstrates why rendering is or is not needed.
Make parsing and validation explicit
A parser maps source material into a schema; a validator checks the schema's meaning for the job. For example, a field may be present but refer to a different currency, seller or timestamp. Separate those checks and preserve a parser or mapping version with observations.
When extraction rules change, run known fixtures before increasing collection volume. If the provider returns structured data, still check required fields, types and business invariants. A managed parser reduces some implementation work, but your application remains responsible for deciding which records can support its decisions.
Integrate through a narrow contract
Place an application adapter between the service response and downstream processing. Map the verified response into a small internal result model with success, missing data and failure represented distinctly. Keep source URL, actual collection time and enough sanitized diagnostic context for review.
Use the documented authentication and request shape from the real KAIROXO integration. Treat timeout, retry and rate behavior as contract questions to test rather than borrowing another provider's defaults. Preserve request or job identifiers where available, and prevent a job retry from creating duplicate downstream records.
Evaluate operational value
Measure usable records, freshness, elapsed time, retry attempts and the work required to maintain the pipeline. A raw request count leaves out parsing errors and missing data. Use one bounded pilot to compare a managed path with an existing worker under equivalent conditions.
Record what the pilot did not test, including regions, page types and peak loads. Keep current pricing assumptions separate from technical acceptance. As the target changes, rerun the representative sample and update the adapter deliberately rather than silently changing the meaning of a successful result.