
Web Data Provenance for RAG: Connect Answers to Evidence
Preserve source versions, extraction lineage and chunk identifiers so an AI answer can point to the evidence that actually supported it.
KAIROXO
Web data provenance connects a retrieved passage to the source observation that produced it. In a RAG system, that connection matters as much as the text itself. A convincing answer with a plausible URL is not enough if the URL now contains different material or the cited passage never supported the claim.
Build provenance while collecting and transforming data, not as a final formatting step. The application should be able to follow an answer back through its retrieved chunks, extraction version and source snapshot. This does not require preserving every byte forever, but it does require explicit identifiers, retention choices and a record of the transformations you actually performed.
Preserve the source observation
For each permitted source, record the requested URL, final URL after approved redirects, collection time, response status and relevant content type. Store the source's claimed update time separately if available; it is not the same as the time your collector observed the page. Use a content hash or immutable snapshot identifier to distinguish versions instead of relying on a mutable URL alone.
Keep the request context needed to explain the representation, such as language and market profile, without storing unnecessary secrets or personal information. Two requests to the same URL can return different material. If retention rules allow a bounded snapshot, preserve it with access controls. Otherwise keep the strongest permitted evidence and make the limitation visible to downstream users.
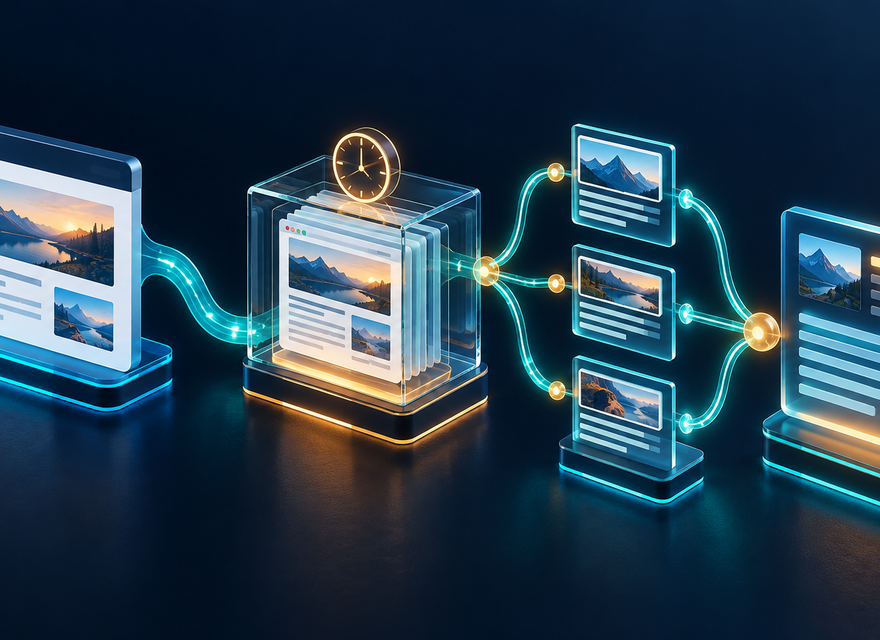
Track transformations as first-class records
An extractor may remove navigation, preserve headings, normalize whitespace and convert tables. Record the extractor version and the relationship between the output document and source version. When a rule changes, you should be able to explain which documents were rebuilt. A clean Markdown file is useful, but its appearance alone does not prove that it accurately represents the source.
Assign stable document and chunk identifiers according to a documented policy. A chunk should refer to its parent document version, section or offset where feasible, and extraction version. Do not reuse the same identifier for unrelated text simply because it occupied the same position in a later crawl. Consistent identity is what makes selective reindexing and meaningful citations possible.
Keep freshness and indexing state separate
Collection time, source update time, transformation time and index availability answer different questions. A page observed today may not have changed for months. A document transformed successfully may still be waiting for indexing. Avoid compressing those states into one generic updated timestamp, because a downstream answer may otherwise claim freshness that the retrieval index does not yet have.
When content changes, replace or invalidate the affected chunks in a controlled way. Track which source versions are active in the index and which are historical evidence. A failed refresh should not relabel an older chunk as newly observed. Your application can continue serving historical material when appropriate, but it should preserve its age and expose uncertainty where the question depends on current information.
Carry evidence into the answer
Stage | Identity to preserve | Review question |
|---|---|---|
Source observation | URL, snapshot or hash, observed time | What representation was collected? |
Extraction | Document version and extractor version | How was text produced? |
Chunking and indexing | Chunk ID and parent version | What can retrieval return? |
Retrieval | Returned chunk IDs and ranking context | What evidence reached the answer step? |
Answer | Claim-to-evidence references | Does the cited passage support the claim? |
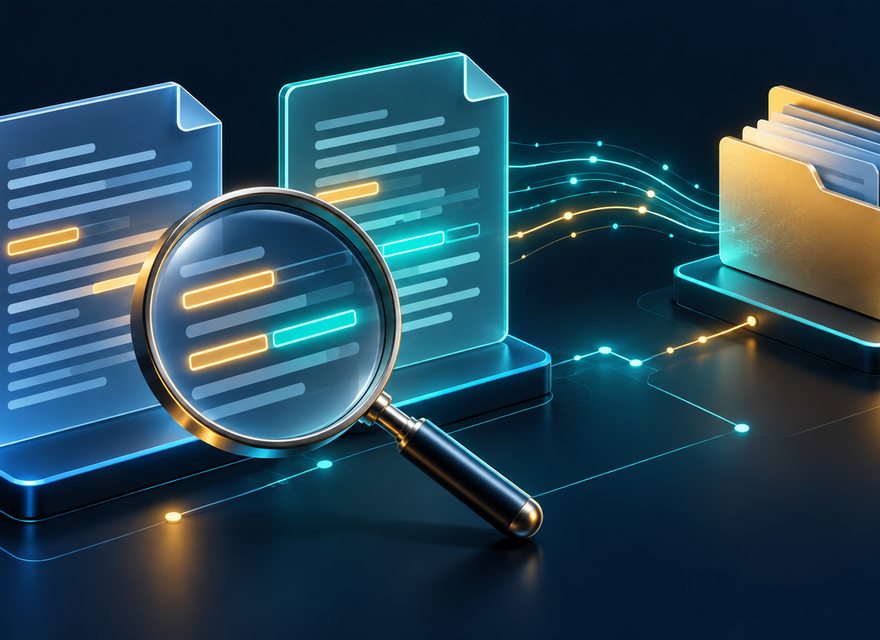
Treat citations as structured application data, not merely text the model invents. Give the answer step only the source identifiers that were actually retrieved, then validate that its references belong to that set. A citation can identify a relevant source without supporting every sentence beside it, so evidence review should check the relationship between claim and passage rather than only the existence of a link.
For sensitive or frequently changing decisions, keep a review path to the exact source version. If a user opens the live URL and sees different content, the system should still explain which observation supported the answer. Clearly distinguish a current source link from an archived evidence reference, and avoid presenting unavailable evidence as if a reviewer had verified it.
Treat collected content as data
Web pages can contain instructions addressed to automated agents, hidden text or material irrelevant to the user's question. Those strings are source data, not permission to change the application's behavior. Keep extraction and retrieval boundaries clear, and do not allow page text to choose tools, reveal credentials or override the system's operating rules.
Evaluate the pipeline with cases that include changed pages, duplicate passages, missing sources and contradictory evidence. Check source coverage, extraction accuracy, retrieval relevance and citation support separately. A high-quality answer on one static demo does not establish that updates, removals and failures are handled correctly throughout the provenance chain.